How you'd work
Small pods, direct access, no account layer.
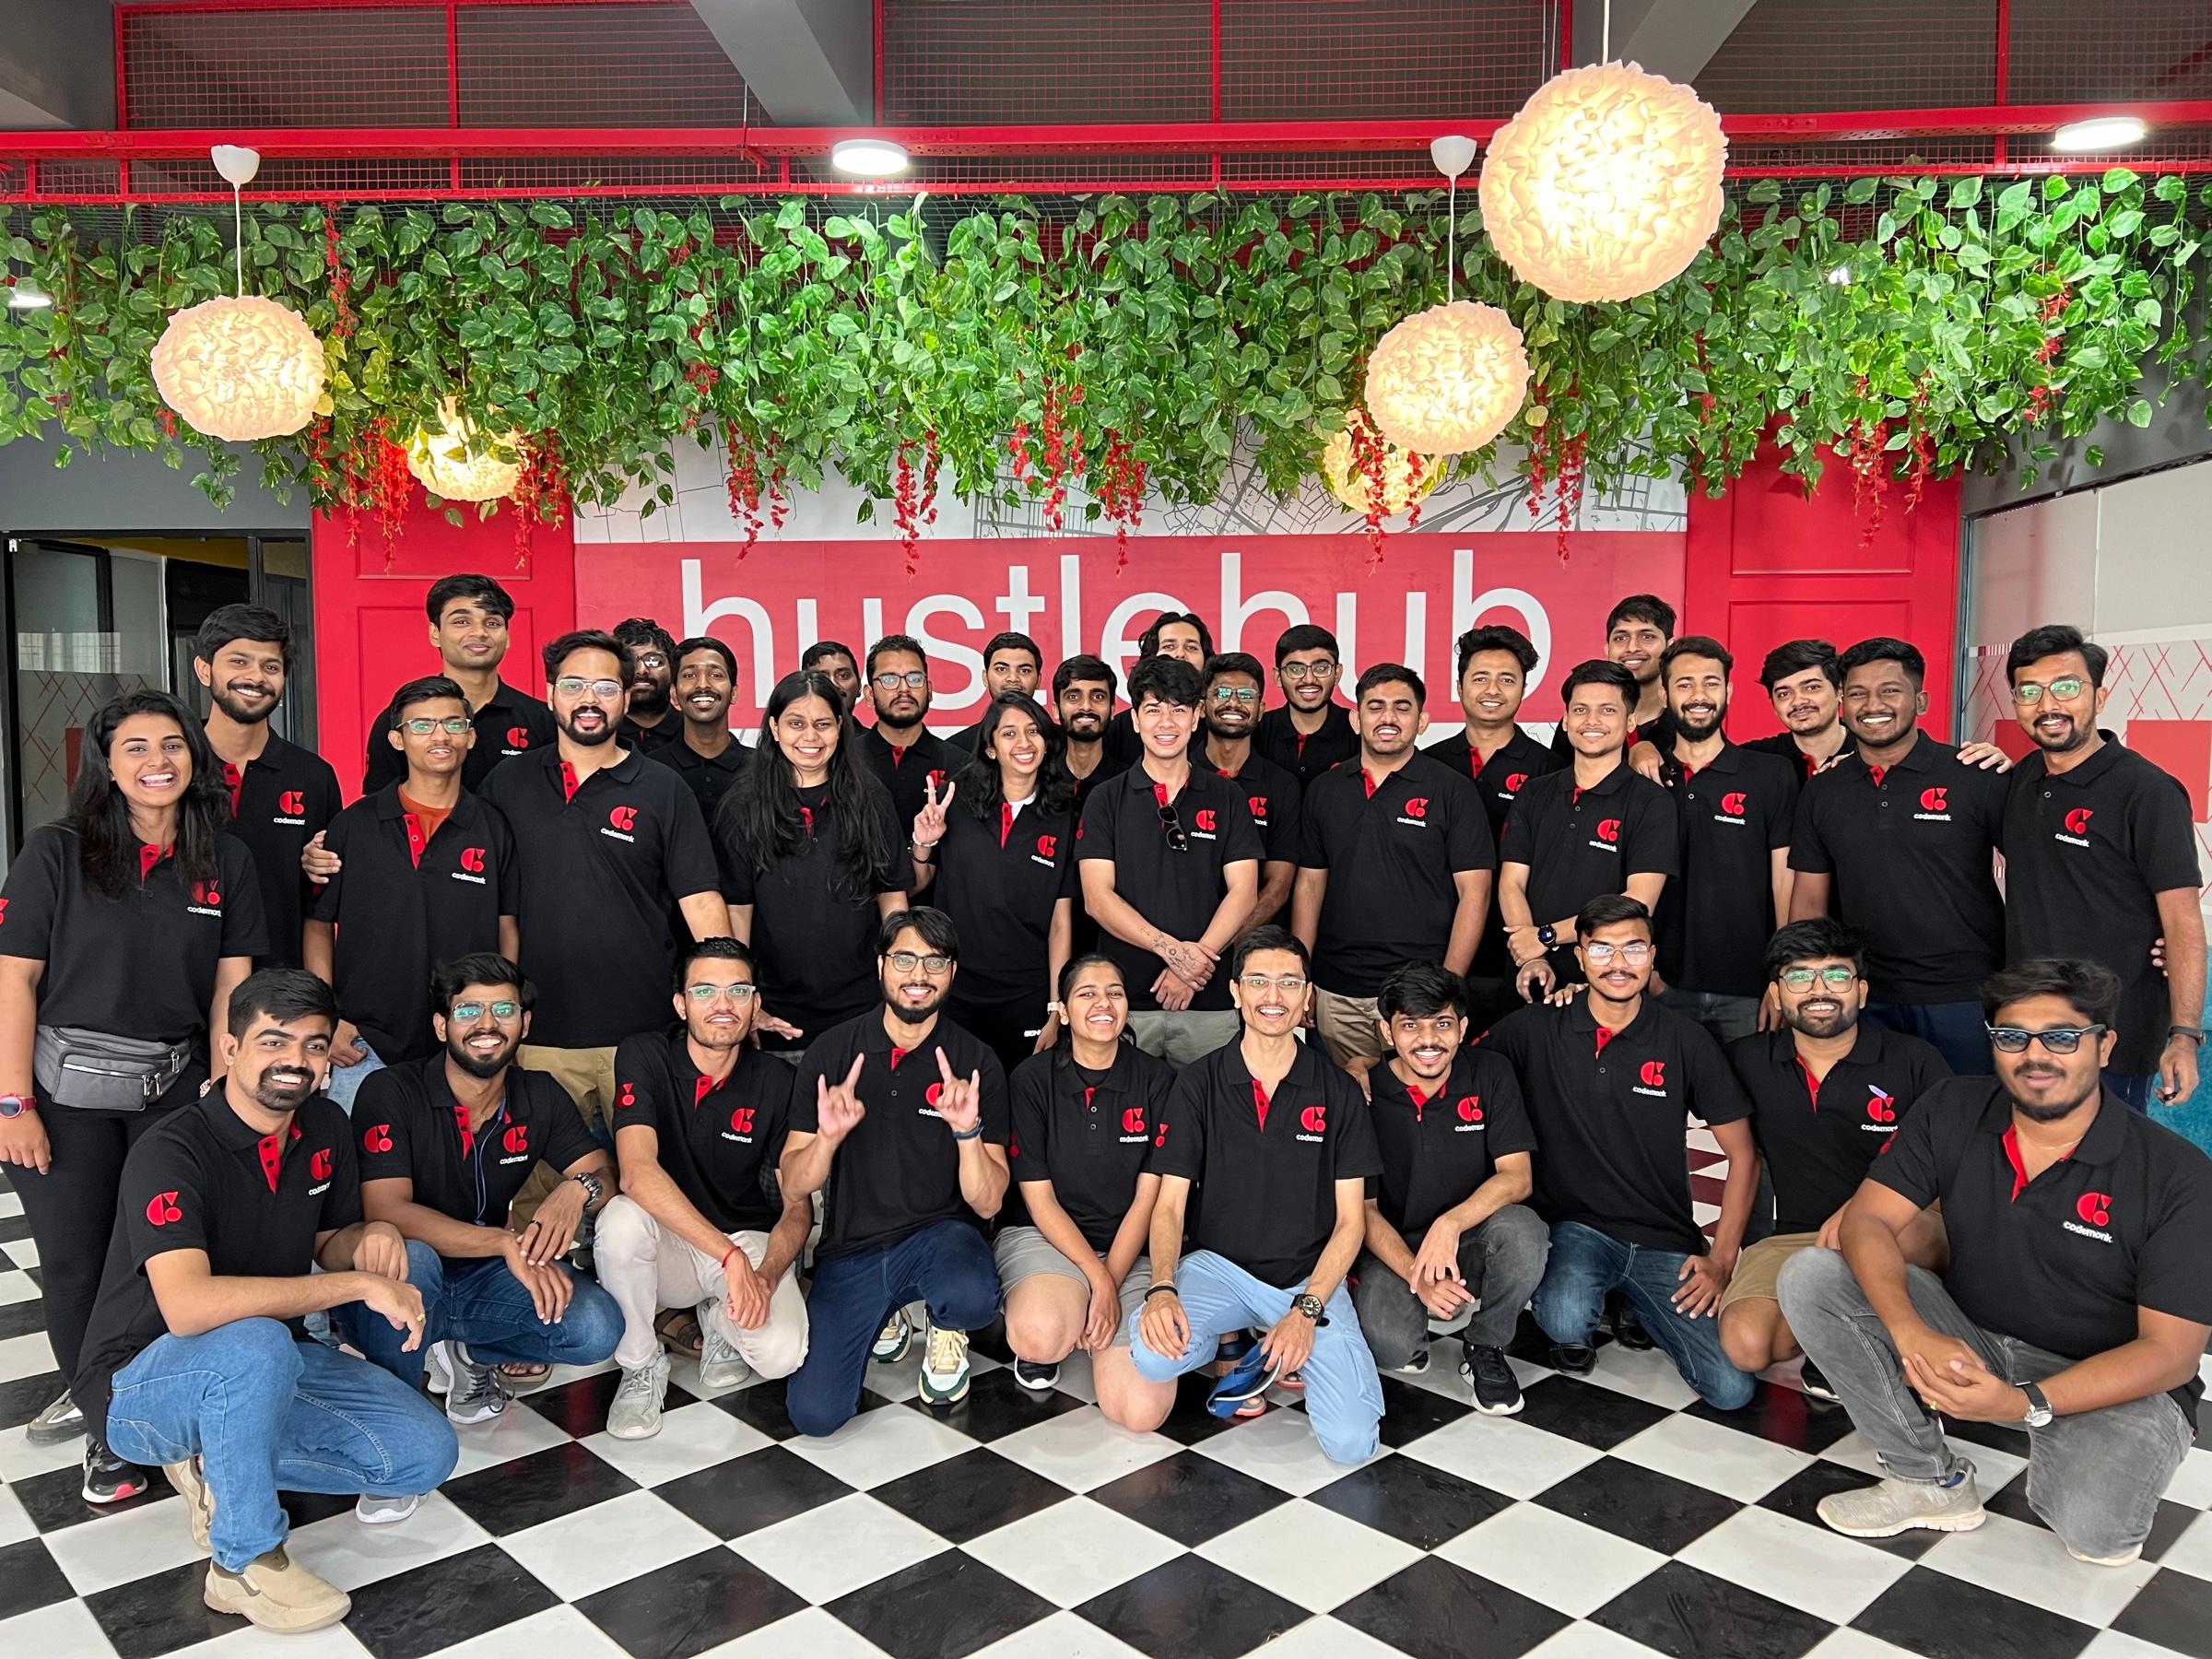
You'll work in a dedicated pod of 3–6 people spanning design, engineering, and ML — embedded with the client, not rotating through a bench. You'll talk directly to the client's engineers and stakeholders, not through an account manager relaying messages. Most people here have shipped more than one production system since joining.
Who you talk to
You work directly with the engineers and designers on your project — not a separate account manager relaying messages.
Team structure
Dedicated pods, sized to the project. We don't staff by the bench — the same people stay on from kickoff to production.
Project length
Engagements range from a focused 6–8 week build to multi-year platform partnerships — several clients have stayed with us for years.
Requirements
What we're actually looking for.
We are seeking a proactive Site Reliability Engineer (SRE) with 2 to 5 years of hands-on experience to maintain high availability, scalability, and performance across our AWS cloud ecosystem. In this role, you will bridge software engineering and operations by building automated delivery pipelines, implementing proactive monitoring, managing containerized applications, and driving incident response protocols.
Key Responsibilities
• Reliability & Incident Management: Monitor production systems, lead operational triage, analyze root causes (RCA), and implement preventative measures to ensure system availability and performance.
• Application Performance Analysis: Analyze application metrics to identify performance bottlenecks and reliability risks, and work with development teams to resolve them.
• Cloud Infrastructure & Containerization: Manage and support AWS core compute and networking services (EC2, ECS Fargate, S3, VPC, Route 53). Maintain containerized workflows using Docker.
• Automation & IaC: Write and maintain Infrastructure as Code using AWS CloudFormation or Terraform to automate infrastructure provisioning and reduce operational toil.
• CI/CD Pipeline Support: Maintain and optimize automated build and deployment pipelines using Jenkins and shell/OS scripting.
• Observability & Alerting: Configure metrics, log aggregation, and alerting frameworks using Datadog or AWS CloudWatch to maintain proactive platform health monitoring.
• Cloud Security & Quality Governance: Maintain cloud perimeter security using AWS WAF and AWS GuardDuty, and assist with code quality and license compliance tools.
Must-Have Qualifications & Skills
• Experience: 2 to 5 years of hands-on experience in SRE, DevOps, or Cloud Infrastructure Operations.
• Scripting: Strong scripting proficiency (Bash, PowerShell, or Python) for task automation, system support, and reducing operational toil.
• Containerization: Hands-on expertise with Docker for containerizing applications.
• Infrastructure as Code (IaC): Working experience with AWS CloudFormation or Terraform.
• AWS Core Services & Networking: Practical experience with VPC, Route 53, EC2, ECS Fargate, S3, AWS WAF, and AWS GuardDuty.
• CI/CD & Automation: Experience configuring and maintaining deployment pipelines in Jenkins.
• Observability: Practical experience establishing metrics, logs, and alerts in Datadog or AWS CloudWatch.
• Application Metrics & Performance Analysis: Deep knowledge of monitoring and interpreting application metrics (latency, throughput, error rates, resource utilization) to detect anomalies, diagnose performance issues, and drive corrective action.
Good-to-Have Skills
• Programming Experience (Preferred): Hands-on programming experience in any language (C# or Python preferred), ideally at least 1 year of software development.
• AI in DevOps / Automation: Familiarity with integrating AI tools, protocols, or agents into DevOps workflows and operational automation.
• Identity & Access Management: Experience with Active Directory management.
• Code Quality & Security Tools: Familiarity with, or administration experience in, SonarQube and Mend (formerly WhiteSource).
• Modern CI/CD: Exposure to GitHub Actions.
• Enterprise Governance: Basic understanding of AWS Control Tower and AWS Security Hub.
Core Competencies
• Strong analytical and troubleshooting mindset for incident triage.
• Drive to automate repetitive manual tasks and eliminate operational toil.
• Clear communication skills to collaborate with development teams and operational stakeholders
Compensation & benefits
Benefits that come with the role.
Compensation is discussed and finalised directly with you at the offer stage, based on experience and scope.
Learning & development
An annual budget for courses, conferences, or certifications — used at your discretion, not pre-approved case by case.
Flexible working hours
Core collaboration hours with the client's team; the rest of your day is yours to structure.
Health coverage
Comprehensive medical insurance for you and your dependents from day one.
Ownership from day one
You're on the pod that ships the system — not a bench waiting for staffing.
Meet the team
Some of the team you'd be joining.
“You're not maintaining someone else's roadmap here — you own the system, from architecture to the 2am page. That's what makes the engineering here different from most services work.”
Hiring process
Four steps, no surprises.
Telephonic Screening
A 20–30 minute call with our talent team about your background and the role — not a script, a conversation.
Assignment
A scoped take-home, typically 3–4 hours, built around a real class of problem we work on — designed to see how you think, not to extract free work.
Technical Rounds
Two rounds with engineers you'd actually work with — one on system design, one on your assignment and past work.
Cultural Round
A conversation with leadership about how you work and what you're looking for next.
Most candidates hear back within 2 weeks of their final interview.
Ready to build this?
Applications go straight to our team — no recruiter queue in between.